OpenTelemetry vs. Prometheus: Key Differences & Use Cases
Compare OpenTelemetry and Prometheus across instrumentation, collection, storage, and alerting, and learn when to use each one or both together.

OpenTelemetry and Prometheus both collect metrics, but they handle different parts of monitoring. Prometheus stores metrics so you can query them and set alerts, while OpenTelemetry collects metrics alongside logs and traces and sends that data to a backend. The two can also work together, with OpenTelemetry sending metrics to Prometheus.
This article compares their approaches to instrumentation, data collection, storage, querying, and alerting. It also covers their key use cases and shows how to integrate OpenTelemetry with Prometheus.
What Is OpenTelemetry?
OpenTelemetry is an open-source, vendor-neutral framework for generating, collecting, and exporting metrics, logs, and traces. It standardizes how applications produce telemetry and how that data reaches observability backends. Its main components include:
- APIs: Define how applications record telemetry without tying instrumentation to a particular backend.
- SDKs: Implement the APIs and handle operations such as sampling, metric aggregation, and exporting telemetry.
- Auto-instrumentation: Instruments supported libraries and frameworks without application code changes. Custom business logic may still require manual instrumentation.
- Collector: Receives, processes, and exports telemetry to one or more backends.
- OTLP: The OpenTelemetry Protocol, which transports metrics, logs, and traces over gRPC or HTTP.
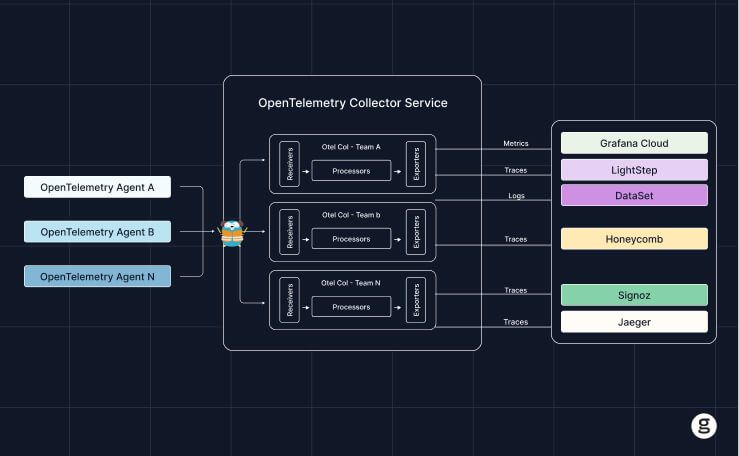
OpenTelemetry doesn't provide persistent telemetry storage, querying, dashboards, or alerting. Those capabilities come from the backend receiving its data.
What Is Prometheus?
Prometheus is an open-source metrics monitoring and alerting system. It collects metrics from applications and infrastructure, stores them as time series, and provides querying and alerting capabilities. Its main components work as follows:
- Metrics collection: Prometheus typically pulls metrics by scraping HTTP endpoints at configured intervals. It discovers targets through Kubernetes and other service discovery integrations.
- Storage and querying: Metrics are stored in a local time-series database (TSDB), where each time series is identified by a metric name and labels. PromQL lets you query and analyze that data.
- Recording and alerting rules: Recording rules precompute frequently used queries, while alerting rules evaluate conditions and forward alerts to Alertmanager for grouping, deduplication, silencing, and notification routing.
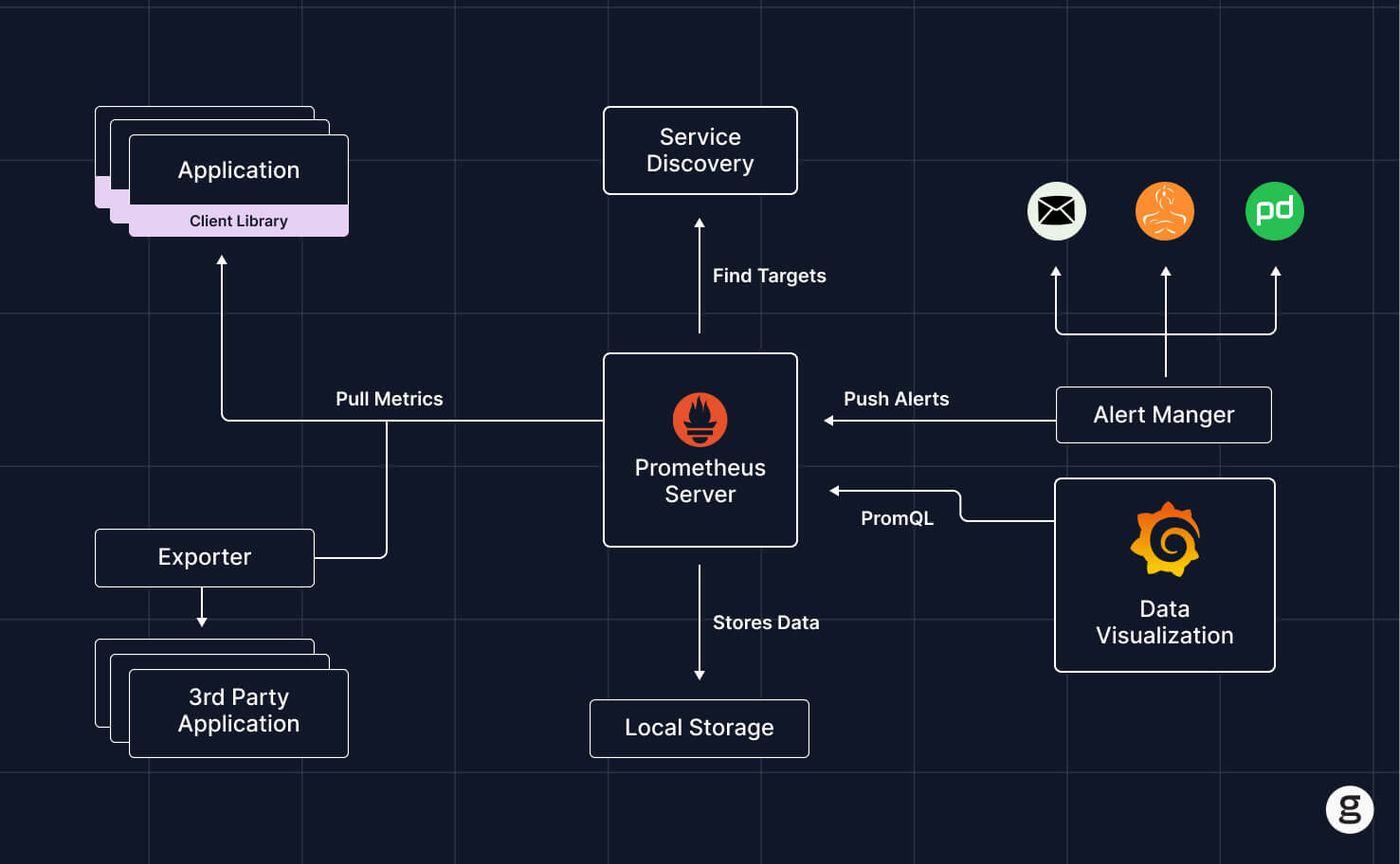
Prometheus includes a basic expression browser for exploring metrics, while Grafana provides more extensive dashboards. Unlike OpenTelemetry, Prometheus focuses on metrics rather than collecting logs or distributed traces. It can attach trace identifiers to metric exemplars, but the actual traces must be stored in another system.
OpenTelemetry vs. Prometheus: Key Differences
OpenTelemetry and Prometheus differ in the telemetry they support, how they collect it, and what they do with the data after collection.
Instrumentation and Telemetry Coverage
Prometheus client libraries instrument applications to expose metrics through HTTP endpoints, typically /metrics. Many Kubernetes components and applications already expose metrics in this format, while exporters make metrics available from systems that don't provide them directly.
OpenTelemetry supports metrics, logs, and distributed traces through its APIs, SDKs, and Collector. Applications can share resource attributes such as service.name across these signals, helping observability backends associate telemetry with the same service. Auto-instrumentation also captures supported HTTP, RPC, and database operations without application code changes, while manual instrumentation provides additional application-specific context.
You don't need to replace existing Prometheus instrumentation to adopt OpenTelemetry. The Collector's prometheus receiver can scrape the same endpoints, allowing you to introduce distributed tracing and other telemetry alongside your existing metrics.
Push vs. Pull Data Collection
Prometheus primarily pulls metrics from HTTP endpoints at configured intervals. Service discovery determines which targets to scrape, while the up metric indicates whether each scrape succeeds. Prometheus also handles stale series when targets stop reporting.
OpenTelemetry SDKs typically export metrics over OTLP at regular intervals. Unlike Prometheus scraping, an OTLP push pipeline doesn't maintain a scrape target list or automatically generate an up metric. You need separate checks to detect services that stop exporting telemetry.
Both technologies also support other collection patterns:
- OpenTelemetry Collector scraping: The
prometheusreceiver discovers and scrapes Prometheus endpoints, including targets configured through Kubernetes service discovery. - Prometheus OTLP ingestion: Prometheus accepts OTLP metrics over HTTP at
/api/v1/otlp/v1/metricswhen started with--web.enable-otlp-receiver. This receiver is disabled by default.
The difference matters when monitoring collection health. Prometheus provides scrape status for pulled metrics, while an OTLP-based pipeline requires monitoring its exporters, receivers, and data flow.
Storage, Querying, and Alerting
Prometheus stores metrics in a local time-series database (TSDB), using a write-ahead log to protect recent samples. You can query stored metrics with PromQL, precompute queries using recording rules, and evaluate alerting conditions. Alertmanager handles notification routing, grouping, and silencing.
OpenTelemetry doesn't include these backend capabilities. The system receiving its telemetry determines how data is stored, queried, visualized, and used for alerting.
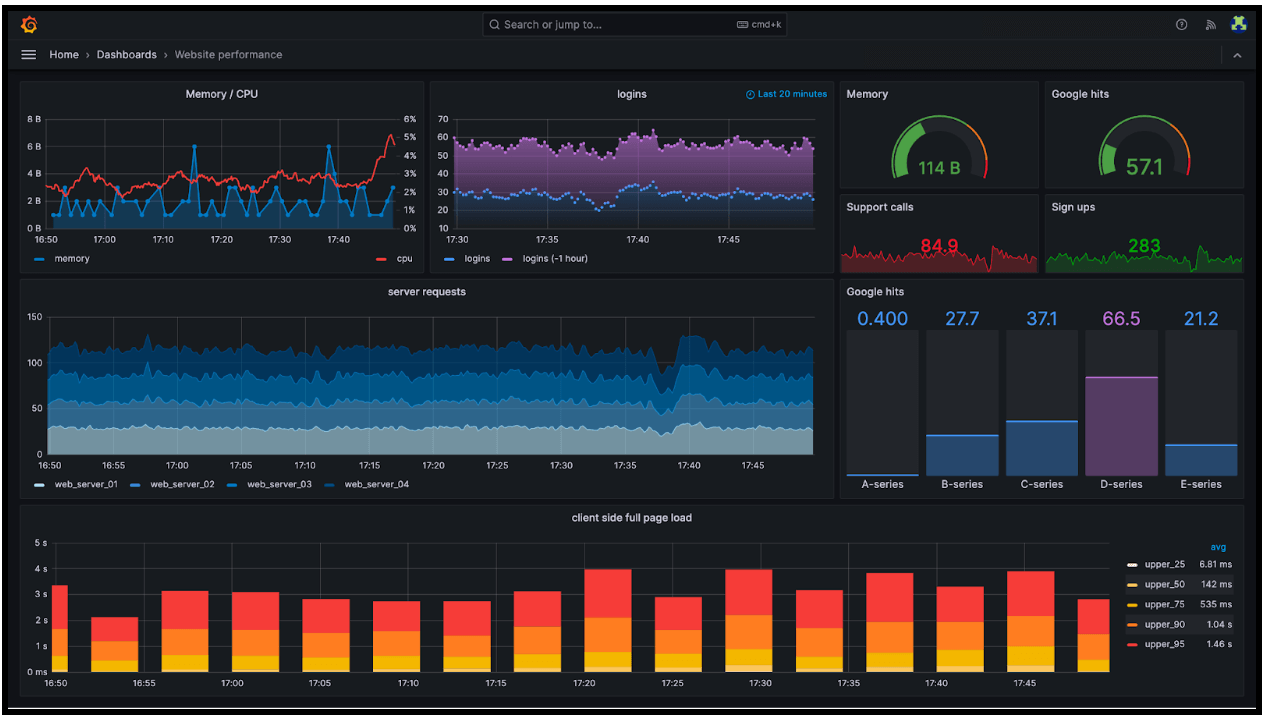
Grafana provides dashboards and exploration for Prometheus and other data sources. For longer retention or distributed metrics storage, systems such as Thanos, Cortex, Grafana Mimir, and VictoriaMetrics extend or provide alternatives to the standard Prometheus storage architecture.
Scalability and Performance
Prometheus resource usage depends on the number of active time series, scrape frequency, label cardinality, and retention settings. Each unique combination of metric name and labels creates another series, so high-cardinality labels increase memory, storage, and processing requirements.
A single Prometheus server can handle substantial workloads, but larger deployments may use federation or Remote Write to distribute metrics across systems. Remote Write also consumes additional memory and network resources for buffering and transmission.
OpenTelemetry Collector resource usage depends on incoming telemetry volume, configured processors, and export throughput. The memory_limiter processor helps control memory consumption, while batching and exporter queues help manage data transmission and temporary backend failures.
Collector scaling requires additional care when scraping Prometheus endpoints. If multiple Collectors run the same scrape configuration, each replica collects the same targets. You need to partition those targets manually or use the OpenTelemetry Operator's Target Allocator to distribute scraping across replicas.
Neither approach is inherently faster or more resource-efficient. Their performance depends on the collection architecture, telemetry volume, and workload.
Metric Formats and Compatibility
OpenTelemetry and Prometheus use different protocols and metric representations. Three formats matter when connecting them:
- OpenMetrics: A metrics exposition format used to expose metrics for scraping.
- OTLP: The OpenTelemetry Protocol, which transports metrics, logs, and traces over gRPC or HTTP.
- Prometheus Remote Write: A protocol for sending metrics to compatible remote storage systems.
Their metric data models also differ. Prometheus identifies time series using metric names and labels, including job and instance. OpenTelemetry separates resource attributes, such as service.name and service.instance.id, from attributes attached to individual metric data points.
When Prometheus ingests OTLP metrics, it maps service.name and service.namespace to job, and service.instance.id to instance. Other resource attributes generally appear in the target_info metric unless specific attributes are promoted to labels using promote_resource_attributes.
Metric names can also change during translation. With the default UnderscoreEscapingWithSuffixes strategy, an OpenTelemetry histogram named http.server.request.duration, measured in seconds, becomes the Prometheus metric family http_server_request_duration_seconds, with series such as http_server_request_duration_seconds_count.
Finally, Prometheus traditionally expects cumulative counters, while OpenTelemetry supports both cumulative and delta temporality. Delta metrics may require conversion before ingestion, although Prometheus also provides experimental delta-ingestion options. Using cumulative temporality avoids these compatibility issues for standard Prometheus monitoring.
The OpenTelemetry metrics guide covers metric instruments and aggregation temporality in more detail.
How to Use OpenTelemetry and Prometheus Together
OpenTelemetry and Prometheus can exchange metrics in both directions. The OpenTelemetry Collector can scrape existing Prometheus endpoints and forward the data to another backend, while Prometheus can receive metrics exported through OTLP. Logs and traces still need a separate backend because Prometheus only stores metrics.
Scrape Prometheus Metrics With the OpenTelemetry Collector
This approach keeps your existing /metrics endpoints and uses the OpenTelemetry Collector to scrape and export their metrics. The data flows from the Prometheus endpoint through the Collector to an OTLP-compatible backend, without requiring changes to application instrumentation.
- Identify the Prometheus targets you want to scrape and add their
scrape_configsto the Collector'sprometheusreceiver. Escape$characters as$$where necessary because the Collector interprets them as environment variable references. - Remove Prometheus server settings such as
remote_write,remote_read, andrule_filesfrom the receiver configuration, since these aren't supported. - Configure the
memory_limiterandbatchprocessors to manage memory consumption and group data before export. - Add an
otlp_httpexporter pointing to your metrics backend, then connect the components underservice.pipelines.metrics.
The following example scrapes metrics every 15 seconds and forwards them to an OTLP-compatible backend:
Replace the target and backend endpoint with your actual addresses, and configure any authentication required by the backend. The percentage-based memory limits also need to be appropriate for the Collector's available memory.
To verify ingestion, query the destination backend for a metric exposed by my-service. Check its labels or resource attributes and inspect the Collector's otelcol_exporter_queue_size, otelcol_exporter_queue_capacity, and exporter failure metrics if data is missing.
Avoid running multiple Collector replicas with identical scrape configurations. Each replica would scrape the same targets, producing duplicate data. For Kubernetes deployments, the OpenTelemetry Operator's Target Allocator can distribute scrape targets across Collectors and integrate with existing ServiceMonitor and PodMonitor resources.
Send OpenTelemetry Metrics to Prometheus Using OTLP
Prometheus can also receive metrics directly from OpenTelemetry-instrumented applications through its OTLP HTTP receiver. This works for smaller deployments, although the receiver isn't intended to replace Prometheus's regular scraping mechanism at high ingestion volumes.
1. Enable the OTLP receiver when starting Prometheus:
This enables the metrics endpoint at /api/v1/otlp/v1/metrics.
2. Configure resource attributes in prometheus.yml if you need additional labels for filtering and querying:
Prometheus already derives the job and instance labels from OpenTelemetry's service identity attributes. If your pipeline delivers samples out of order, you can separately configure storage.tsdb.out_of_order_time_window, using a window appropriate for the expected delay.
3. Configure your instrumented application to export metrics over OTLP HTTP/protobuf:
The metrics-specific endpoint variable specifies the complete receiving URL. Alternatively, you can set OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:9090/api/v1/otlp, which allows an OTLP/HTTP SDK to append /v1/metrics automatically.
Assign a unique service.instance.id to each application instance. If Prometheus is the application's only telemetry destination, disable the unused trace and log exporters:
4. Verify that Prometheus receives the service's metrics. First, check for the service identity:
If the application emits the OpenTelemetry HTTP server request-duration histogram, you can also query its translated counter series:
For production deployments, an intermediary Collector provides batching, retries, queues, and centralized routing. It doesn't remove the Prometheus OTLP receiver's ingestion limitations, so retain scraping or consider another compatible metrics backend when handling larger workloads.
You can also expose Collector metrics through its prometheus exporter for Prometheus to scrape, or use the prometheus_remote_write exporter to send metrics to compatible Remote Write receivers. The latter requires appropriate metric temporality and a receiver configured to accept Remote Write traffic.
When Should You Use OpenTelemetry, Prometheus, or Both?
The right choice depends on what you need to monitor and the tools already in your stack. Prometheus is a good fit for metrics monitoring and alerting, while OpenTelemetry becomes useful when you need traces, logs, or telemetry routing across different backends. You can also add OpenTelemetry to an existing Prometheus deployment without replacing its metrics collection.
Here are the common use cases for each approach:
Using OpenTelemetry and Prometheus together also requires coordinating how metrics are collected and exported. Avoid scraping the same targets into the same backend twice, and be selective about which OpenTelemetry resource attributes become Prometheus labels to prevent unnecessary increases in time-series cardinality. You'll also need to monitor Collector resources and exporter failures as telemetry volume grows.
Full-Stack Observability With groundcover
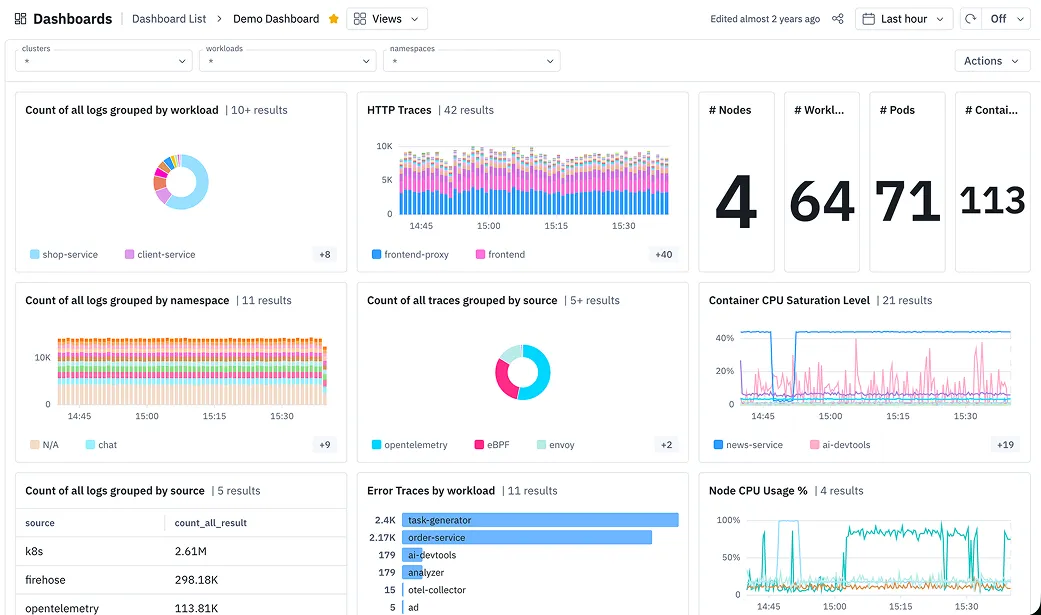
groundcover brings OpenTelemetry and Prometheus data into the same observability platform alongside telemetry collected by its eBPF sensor. It provides storage, querying, dashboards, alerting, and application performance monitoring (APM) without requiring you to replace your existing instrumentation or metrics collection setup.
Integrating Existing Telemetry With groundcover
Existing OpenTelemetry Collectors can send metrics, logs, and traces to groundcover using an OTLP exporter configured with your BYOC endpoint and ingestion key. The Collector can continue exporting telemetry to other backends, so your existing pipelines don't need to be replaced. For Prometheus metrics, groundcover supports Remote Write and scraping Kubernetes metrics endpoints. You can forward metrics from an existing Prometheus deployment or configure groundcover to scrape annotated pods and targets defined through ServiceMonitor or PodMonitor resources.
groundcover stores metrics in VictoriaMetrics, which supports PromQL, while ClickHouse handles logs, traces, and Kubernetes events. These data sources power its dashboards, queries, alerts, and APM views, including application performance metrics derived from OpenTelemetry traces for services without an eBPF sensor. With its Bring Your Own Cloud (BYOC) architecture, the observability backend runs in your cloud environment while groundcover manages the hosted control plane and UI. This keeps your telemetry within your infrastructure while providing a common interface for investigating metrics, logs, and traces.
Combining eBPF and OpenTelemetry for Broader Visibility
groundcover's eBPF sensor runs as a Kubernetes DaemonSet and captures supported HTTP, database, and network activity without requiring SDKs or application restarts. It can discover traffic from workloads that haven't been instrumented, including supported third-party containers. OpenTelemetry instrumentation adds custom spans and application-specific attributes to groundcover's automatically collected telemetry, bringing application workflows and runtime activity into the same observability platform.
For example, groundcover's eBPF sensor can capture database traffic and errors, including failures caused by a missing database table. OpenTelemetry spans can add application-level context to help trace the requests associated with those failures. groundcover combines both telemetry sources to provide application and infrastructure context during troubleshooting, while its APM views also support services instrumented with OpenTelemetry independently of the sensor. The eBPF sensor requires Kubernetes 1.21 or later and supported Linux nodes running kernel 5.3 or later with BTF/CO-RE support; AWS Fargate isn't supported for sensor deployment. You can test these integrations through groundcover's free BYOC plan, which doesn't require a credit card.
| Difference | OpenTelemetry | Prometheus |
|---|---|---|
| Main function | Telemetry data collection. | Metrics-based monitoring and alerting. |
| Data types supported | Metrics, logs, and traces. | Metrics. |
| Collection model | Push or pull. | Pull. |
| Scalability and performance | No major scalability challenges. | Some scalability challenges due to single-server design. |
| Community and adoption | Very widely used (because there are no major alternatives, except arguably eBPF). | Somewhat less widely used (because there are many alternative monitoring tools). |
Faqs
Partly. The OpenTelemetry Collector can replace Prometheus scraping, but it doesn't provide persistent metrics storage, PromQL querying, or alert evaluation. To remove Prometheus entirely, you'll need another backend that handles those capabilities.
OpenTelemetry generates, collects, and exports metrics, logs, and traces. Prometheus stores metrics and provides PromQL querying and alerting, while Grafana queries data from Prometheus and other sources to provide dashboards, exploration, and alerting. The three tools can work together as part of the same observability stack.
OpenTelemetry adds distributed tracing, log collection, and consistent resource attributes across telemetry signals. Its Collector also lets you process and route data to multiple backends without changing application instrumentation. This makes it useful when your observability requirements extend beyond metrics monitoring.
OpenMetrics is primarily a text-based exposition format for metrics, commonly used to expose data on HTTP endpoints for Prometheus-compatible scrapers. OTLP transports metrics, logs, and traces using Protocol Buffers over gRPC or HTTP, with binary and JSON encoding supported over HTTP. OpenMetrics is suited to exposing metrics for scraping, while OTLP is designed to send telemetry between applications, Collectors, and observability backends.
No. groundcover provides full-stack observability through its eBPF sensor, automatically collecting supported application, network, and infrastructure telemetry from Kubernetes workloads without requiring OpenTelemetry SDKs, a Prometheus server, or application code changes. However, it also integrates with OpenTelemetry and Prometheus, providing a unified platform for monitoring, querying, troubleshooting, and alerting across metrics, logs, and traces.